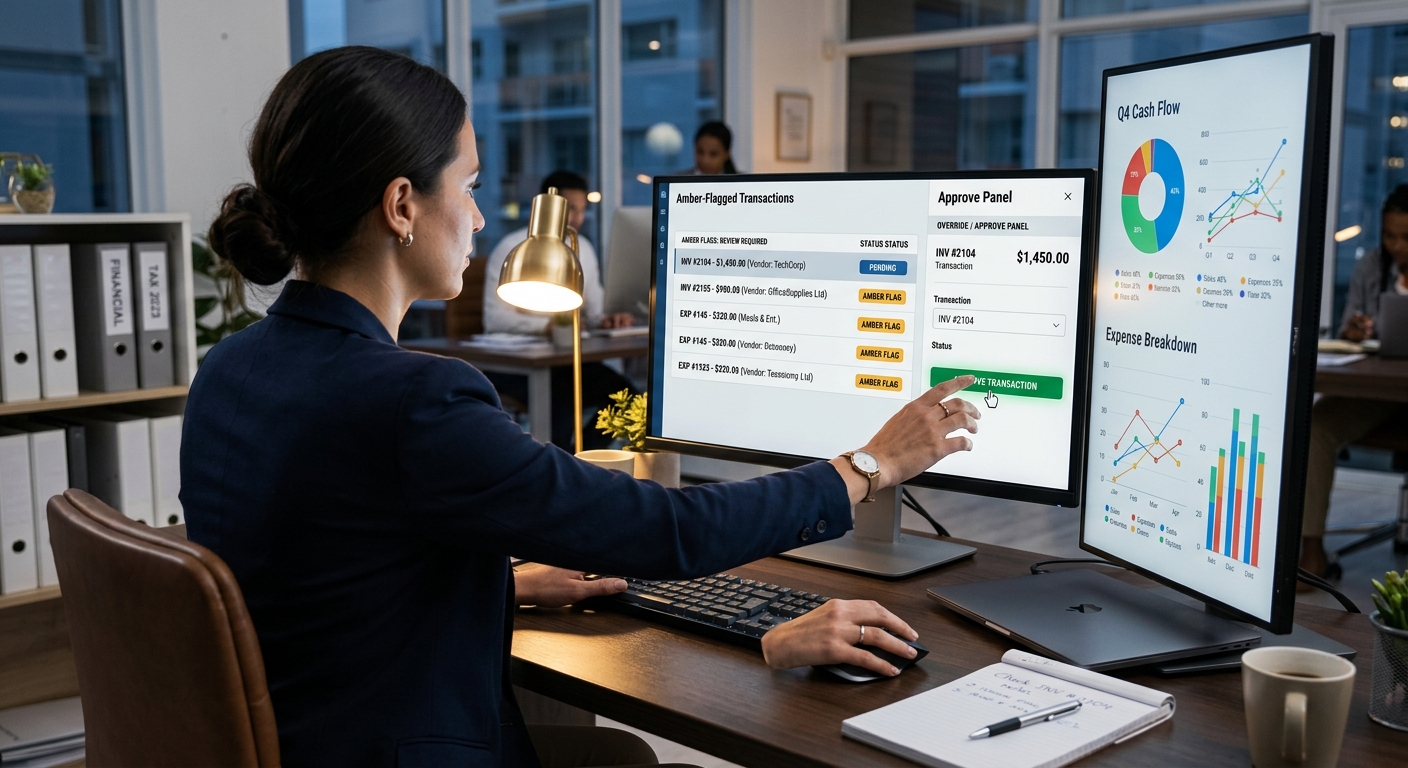
AI bookkeeping fails in a predictable direction: quietly and compounding. The best models still miss roughly one in five full accounting workflows, and errors flow downstream into your P&L, tax filings, and audit trail (DualEntry benchmark, March 10, 2026; CFO.com, April 22, 2026). What separates businesses that benefit from AI from those burned by it isn’t the model they chose — it’s whether anyone built a review layer between the machine’s drafts and their actual ledger.
This guide is that layer’s operating manual: five components, a weekly rhythm, documentation standards, and the staffing math. It pairs with our earlier task-map of where automation belongs (can AI do your bookkeeping) — read that first if you haven’t.
In this article
The Five Components of a Working Review Layer
1. Confidence-based triage. Your platform flags uncertain items; your job is trusting the flag. Field data across 79 companies showed accountants selectively intervening on low-confidence scores — and that selective attention tracked with measurable quality gains (Choi & Xie, June 2026). If your tool can’t express confidence, substitute rules: new vendors, amounts over a threshold, and any transaction matching no prior pattern get human eyes.
2. Exception queue with a service level. Flagged items need an owner and a deadline — reviewed within two business days, or by close, whichever comes first. An exception queue nobody checks is just error storage.
3. Weekly spot-check. Pull one random day from each week and verify every transaction on it. Randomness catches systematic errors your rules miss; predictability trains you to prepare for the check instead of the books.
4. Monthly aggregate review. Before close, scan category totals against trailing averages, reconcile collected tax to deposits, and eyeball the uncleared-items aging. Machine errors concentrate in aggregates even when individual items look plausible.
5. Documented approval. Every human decision leaves a trace: what was flagged, what was changed, who approved it, when. This isn’t bureaucracy — it’s the difference between “the books are right” and “here’s why the books are right,” which is exactly the question an auditor, buyer, or lender asks.
The Weekly Rhythm That Holds It Together
- Daily (5 min): clear yesterday’s exception queue.
- Weekly (15 min): random-day spot-check; approve new vendors permanently once verified.
- Monthly (30–45 min): aggregate review, tax reconciliation, report snapshot, documentation update.
- Quarterly: audit the rules themselves — retire stale vendor mappings, re-test confidence thresholds, verify subscription amounts haven’t crept.
That cadence matches how accuracy actually matures: platforms climb from roughly 87–89% in month one toward 96–98% after a year as corrections accumulate (Finntree, April 9, 2026). Supervision shrinks as trust earns itself.
Documentation Standards That Survive Scrutiny
Keep a running close memo — one document per month, four lines minimum:
- What automation did: transaction counts, auto-match rate, exception volume.
- What humans changed: every override with before/after category.
- Who approved: initials and date per batch, not per transaction.
- What was learned: new rules created, thresholds adjusted.
The point isn’t perfection; it’s reconstruction. Anyone competent should be able to retrace the month from this memo plus system logs. Businesses selling on clean financials — or facing diligence — find this file is worth more than the software subscription that generated it.
When Web Works LLC took over books for a client whose previous “automated” service had no review layer at all, we found eleven months of subscription charges coded to office supplies because one vendor mapping had gone stale after a price change. Nothing flagged it: each charge looked individually plausible. The monthly aggregate check would have caught it in month one. That single anecdote is why our supervision standard starts with aggregates, not line items.
The Staffing Math
A supervised hour covers roughly 250–400 automated transactions at small-business complexity — call it an hour per week for a business doing 1,000–1,500 transactions monthly. Compare that against doing everything manually (Finntree’s benchmark: 45 minutes of manual entry per 100 transactions) and the trade becomes clear: you’re buying back ~95% of the hours while spending focused attention only where judgment pays.
Two failure modes to refuse:
- Reviewing everything. You’ve rebuilt manual bookkeeping with extra software cost.
- Reviewing nothing. DualEntry’s finding applies: a 20% error rate is manageable with validation layers, unmanageable without them.
If neither you nor your team has the hour, that’s precisely what outsourced providers sell — oversight as a product. Our ranking of services shows which bundles include genuine human review versus raw automation (best online bookkeeping services).
Frequently Asked Questions
How much of AI bookkeeping output actually needs human review?
Typically under 10%: low-confidence flags, first-time vendors, vague bank descriptors, owner transactions, and loan-related entries. Recurring merchants and subscriptions run near-perfect and need only sampling.
What happens if nobody reviews AI bookkeeping?
Errors compound silently. The best models fail about one in five full workflows, and misclassifications flow into reports and filings where each one costs more to find — the eleven-month subscription miscoding in our client example is typical.
Who should do the reviewing?
Someone who understands your business context — why an expense might be COGS this month and supplies next month. Software knowledge matters less than judgment about your operations. That’s why oversight is often the first thing owners outsource even while keeping automation in-house; the pillar guide (client bookkeeping solutions) compares those arrangements.
Does review effort decrease over time?
Yes, if corrections feed back into rules and training. Accuracy climbs from ~87–89% toward 96–98% over twelve months on real deployments — but only when every correction becomes permanent learning rather than a one-off fix.
More From Web Works LLC
- Client Bookkeeping Solutions: The Complete Guide for Growing Businesses
- Bookkeeping articles
- Web Works bookkeeping services — automation plus a documented human review layer, run for you monthly.